# /Satoshi:31.0.0/ peers with no service flags and protocol 70015 pushed transactions, then stopped together on Oct 18
**URL:** https://bnoc.xyz/t/satoshi-31-0-0-peers-with-no-service-flags-and-protocol-70015-pushed-transactions-then-stopped-together-on-oct-18/193
**Category:** Observations
**Tags:** p2p
**Created:** [October 20, 2026, 12:18pm UTC](https://bnoc.xyz/t/satoshi-31-0-0-peers-with-no-service-flags-and-protocol-70015-pushed-transactions-then-stopped-together-on-oct-18/193 "2026-10-20T12:18:49Z")
**Posts on this page:** 11
**Page:** 1
### Author:  [@benunskilled](https://bnoc.xyz/u/benunskilled)
#### Post date: [October 20, 2026, 12:18pm UTC](https://bnoc.xyz/t/satoshi-31-0-0-peers-with-no-service-flags-and-protocol-70015-pushed-transactions-then-stopped-together-on-oct-18/193/1 "2026-10-20T12:18:49Z")
My listening node (Core 31.1) got inbound connections from a small fleet announcing `/Satoshi:31.0.0/` that, as far as I can tell, isn’t Bitcoin Core.
**Who:** 6,591 sessions from 22 IPv4 addresses (Oct 6–18), each in a different /16: AWS in 7 regions (17), Tencent (3), Alibaba (1), China Unicom (1). From Sep 16 to 21 the same addresses partly used `/Sat0shi:31.0.0/` (with a zero).
**Why I don’t think it’s Core:**
- No service flags. Core 31 always sets at least `NETWORK_LIMITED | WITNESS` ([init.cpp#L863](https://github.com/bitcoin/bitcoin/blob/v31.0/src/init.cpp#L863)); `NODE_NONE` only appears on private-broadcast connections as `/pynode:0.0.1/`.
- Protocol 70015, while v31 uses 70016 ([protocol\_version.h#L12](https://github.com/bitcoin/bitcoin/blob/v31.0/src/node/protocol_version.h#L12)).
- No `sendcmpct`, which Core sends to every peer at ≥ 70014 ([net\_processing.cpp#L3870-L3876](https://github.com/bitcoin/bitcoin/blob/v31.0/src/net_processing.cpp#L3870-L3876)).
- `tx` messages my node never asked for.
| ended sessions ≥ 60 s, Oct 16–18 | fleet | Core 31.x, tx relay |
| --- | --- | --- |
| sessions / IPs | 712 / 8 | 170 / 122 |
| v2 transport | 0 % | 85 % |
| sends `tx` without my `getdata` | 42 % | 0 % |
| delivered ≥ 1 tx new to my mempool | 79 % | 22 % |
| announced a block (sessions spanning ≥ 1 block) | 0 / 403 | 61 / 95 |
**The stop:** all 11 open sessions, including three that had been connected since Oct 12 and 15, closed between 12:54 and 13:28 UTC on Oct 18. Before that the longest gap between new sessions was 1.4 hours. None has come back to my node since.
Did anyone else see this fleet or the stop, or know who runs it? It looks different from [#17](https://bnoc.xyz/t/17): those peers announce 70016 and behave like 70015, and I found no address overlap.
Caveats: one node; polling `getpeerinfo` every 10 s; I only see the part of the fleet that connected to me.
Happy to share IPs and per-session data privately.
---
### Author:  [@stratospher](https://bnoc.xyz/u/stratospher)
#### Post date: [October 20, 2026, 7:53pm UTC](https://bnoc.xyz/t/satoshi-31-0-0-peers-with-no-service-flags-and-protocol-70015-pushed-transactions-then-stopped-together-on-oct-18/193/2 "2026-10-20T19:53:49Z")
very nice. thanks for sharing! I had encountered this weird user agent as well but hadn’t looked into the details.
it’s interesting that they also reconnect back when we disconnect and end up evicting themselves (like linking lion). I see you’ve mentioned 1.4 hours as the longest time the fleet took to reconnect back - curious what the fleet’s usual reconnection rate is for you? I think I’m seeing 1 sec or less.
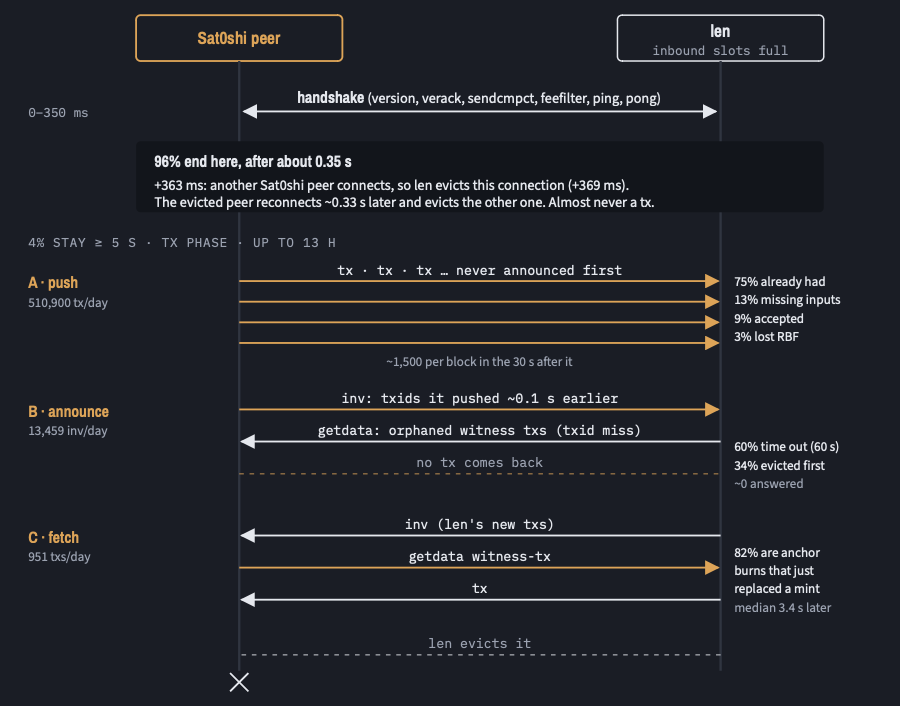
apparently these peers were sending us [runestones](https://www.uncommongoods.top)!
- the UNCOMMON•GOODS minting is still happening (via ordinary gossip relay) but the operator/operation has changed?
- the OP\_RETURN from the transactions which `/Sat0shi:31.0.0/` peers sent us till October 18 had some extra fields and now the minting which gets mined in bitcoin blocks don’t have it anymore.
here’s what 1 of these peers sent node `len` from peer.observer (basically unsolicited runestone tx):
---
### Author:  [@stratospher](https://bnoc.xyz/u/stratospher)
#### Post date: [October 20, 2026, 8:03pm UTC](https://bnoc.xyz/t/satoshi-31-0-0-peers-with-no-service-flags-and-protocol-70015-pushed-transactions-then-stopped-together-on-oct-18/193/3 "2026-10-20T20:03:08Z")
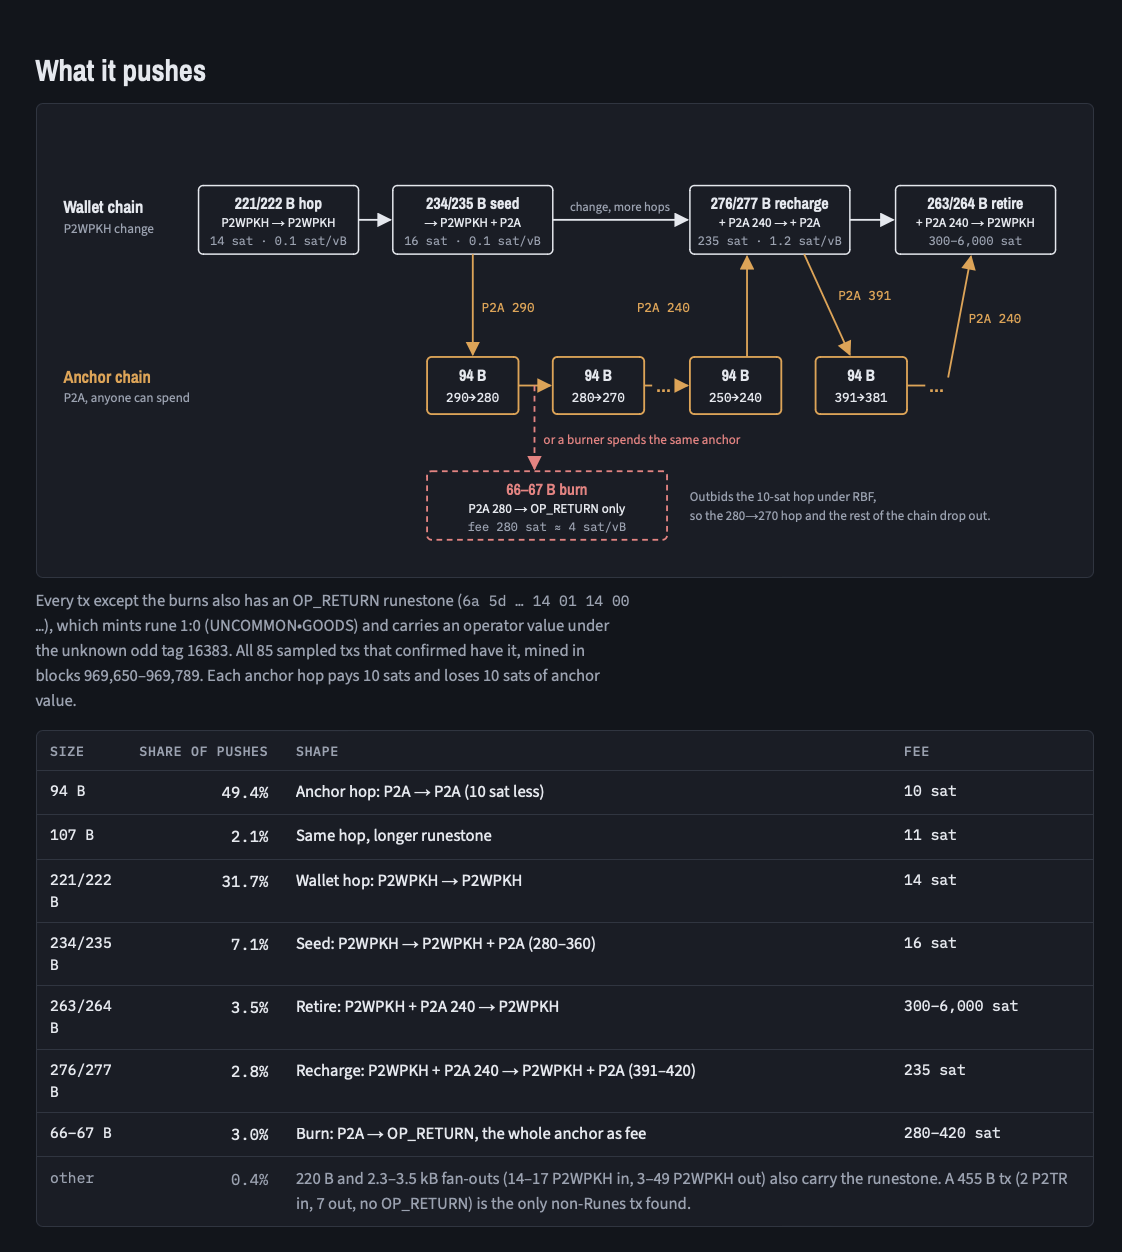
claude also drew this but I don’t know much about P2A. just sharing it here in case it’s interesting for anyone else.
---
### Author:  [@benunskilled](https://bnoc.xyz/u/benunskilled)
#### Post date: [October 21, 2026, 8:20am UTC](https://bnoc.xyz/t/satoshi-31-0-0-peers-with-no-service-flags-and-protocol-70015-pushed-transactions-then-stopped-together-on-oct-18/193/4 "2026-10-21T08:20:47Z")
Thanks! The tx breakdown explains a lot.
On reconnects: I poll getpeerinfo every 10 s, so sessions that end within a second like yours never show up for me. My inbound slots are full too. What I see for Oct 6–18:
- 17 of the 22 IPs held 2–3 connections at once. In 83 % of cases a new connection from an IP appeared and an older one from the same IP was gone within the same poll, which fits the self-eviction you describe.
- Across the fleet, a new visible session started about once a minute (median; 90 % within 7 min). The 1.4 h in my post was the longest of these gaps, not a per-IP reconnect time.
Possibly related to your burn row: a peer announcing /p2aburn:1.0/ (one IPv4 at Tencent, AS132203, not one of the 22) has connected to my node since at least Sep 16 and is still around after Oct 18. No service flags, protocol 70016. In its three longer sessions since Oct 16 it pushed unsolicited tx messages totalling 27,360, 1,080 and 2,700 bytes. All three are exact multiples of 90 (24-byte header + 66-byte tx), so 304, 12 and 30 transactions if each message is one tx. None were new to my mempool. I didn’t log txids, so I can’t confirm they’re P2A burns, but the size matches.
One question: you write /Sat0shi:31.0.0/ with a zero. On my node the same IPs used that spelling only until about Sep 21 and /Satoshi:31.0.0/ after that. Did yours keep the zero until Oct 18?
---
### Author:  [@m4ycon](https://bnoc.xyz/u/m4ycon)
#### Post date: [October 21, 2026, 3:48pm UTC](https://bnoc.xyz/t/satoshi-31-0-0-peers-with-no-service-flags-and-protocol-70015-pushed-transactions-then-stopped-together-on-oct-18/193/5 "2026-10-21T15:48:52Z")
Yesterday, I took a look at those nodes appearing on my node running peer-observer, about `31.0.0 + ver 70015` and `p2aburn*`. The images below show a counter on how many connections those peers opened to us per day, for reference here is the promql that generated this:
```auto
sum by (useragent) (
increase(peerobserver_p2p_version_useragent{useragent=~"/p2aburn.*|/Sat0shi:31.0.0/"}[1d])
)
```
1. 2026-07-03: `p2aburn` “probe” first appearence;
2. 2026-07-14: `p2aburn` non-probe started to appear;
3. 2026-08-03: `Sat0shi:31.0.0` first appearance;
4. 2026-09-22: `Sat0shi:31.0.0` last appearance, in this metric I have no way to filter (also) per protocol (70015), so it stops there;
5. 2026-10-18: after some peaks, `p2aburn` falls to about 30~50 connections per day.
Now, based on logs (with a llm help), here it is the same data that also includes `/Satoshi:31.0.0/ + 70015`:
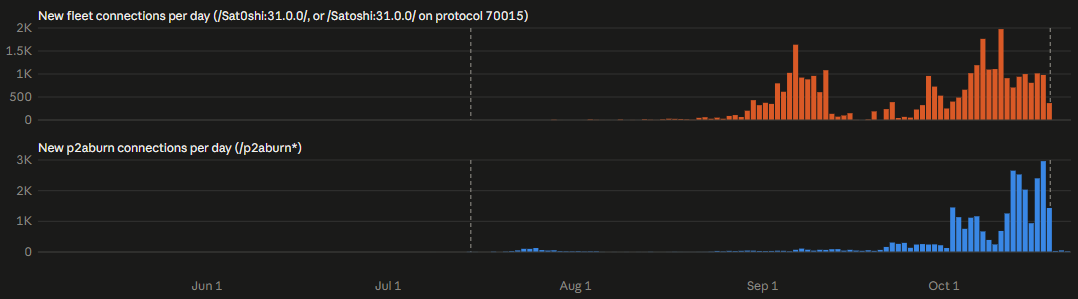
> Note: dashed lines means, first 2026-07-14 (`p2aburn` arrival) and the other is 2026-10-18.
Also, take a look at the volume of tx messages they were compared to the rest of the network:
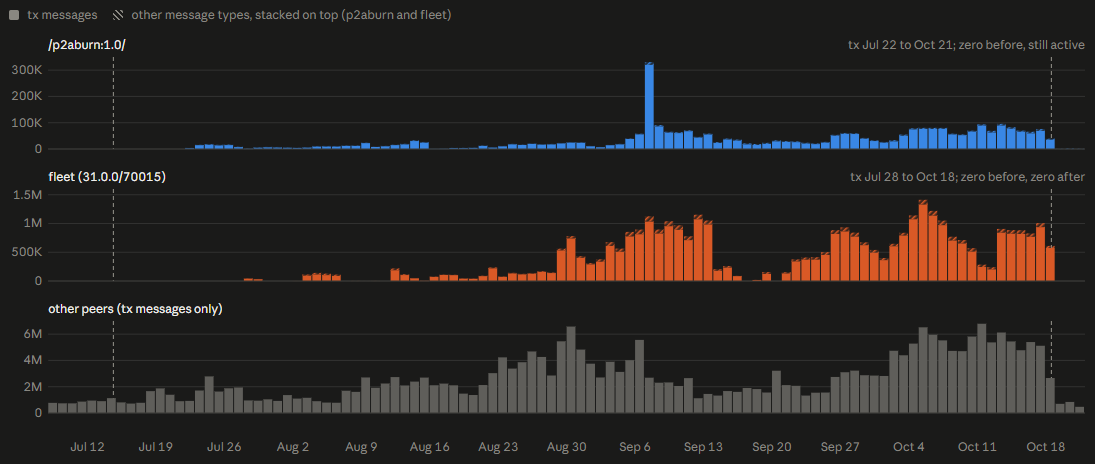
`p2aburn` still active but in a way lower volume than before, unlike fleet which is zero.
I didn’t see any of you mentioning it, but on 2026-10-18 many vps providers had rebooted their machines due to CVE-2026-99999 (including mine), see more at [#189](https://bnoc.xyz/t/effect-of-linux-kernel-cve-2026-99999-cvss-9-3-pwnscape-on-the-bitcoin-network/189). I suppose the operators didn’t realize it yet, maybe at some point they will.
I see some sort of correlation with what’s happening with compact block reconstruction degradation as discussed in [delving#1052](https://delvingbitcoin.org/t/stats-on-compact-block-reconstructions/1052/53?u=m4ycon), I’m still writing a BNOC’s post about it, your report gave me some insights, thank you @benunskilled and @stratospher!
---
### Author:  [@benunskilled](https://bnoc.xyz/u/benunskilled)
#### Post date: [October 22, 2026, 12:40pm UTC](https://bnoc.xyz/t/satoshi-31-0-0-peers-with-no-service-flags-and-protocol-70015-pushed-transactions-then-stopped-together-on-oct-18/193/6 "2026-10-22T12:40:44Z")
Thanks, the timeline is very helpful. Your last /Sat0shi:31.0.0/ on Sep 22 matches my node, when the same addresses switched to /Satoshi:31.0.0/
On the CVE reboots: I’m not sure they explain the stop, at least on my node. From Oct 16 the fleet only reached me from 8 AWS addresses, and AWS said EC2 was not affected and needed no action ([2026-137-AWS](https://aws.amazon.com/security/security-bulletins/2026-137-aws/)). The last sessions from all 8 closed within about a minute (13:27–13:28 UTC on Oct 18), spread over 6 AWS regions on three continents. Host reboots across six regions at the same moment seem unlikely to me, and none of the fleet came back from any address since, so it looks more like something central on the operator’s side. That could still be a reboot, e.g. if their controller ran at one of the providers that did restart, so I can’t rule your idea out.
Looking forward to your post on the compact block side!
---
### Author:  [@b10c](https://bnoc.xyz/u/b10c)
#### Post date: [October 22, 2026, 2:00pm UTC](https://bnoc.xyz/t/satoshi-31-0-0-peers-with-no-service-flags-and-protocol-70015-pushed-transactions-then-stopped-together-on-oct-18/193/7 "2026-10-22T14:00:49Z")
> [@m4ycon](#):
>
> ```auto
> sum by (useragent) (
> increase(peerobserver_p2p_version_useragent{useragent=~"/p2aburn.*|/Sat0shi:31.0.0/"}[1d])
> )
>
> ```
This is how this looks for me (summed up across all my nodes).
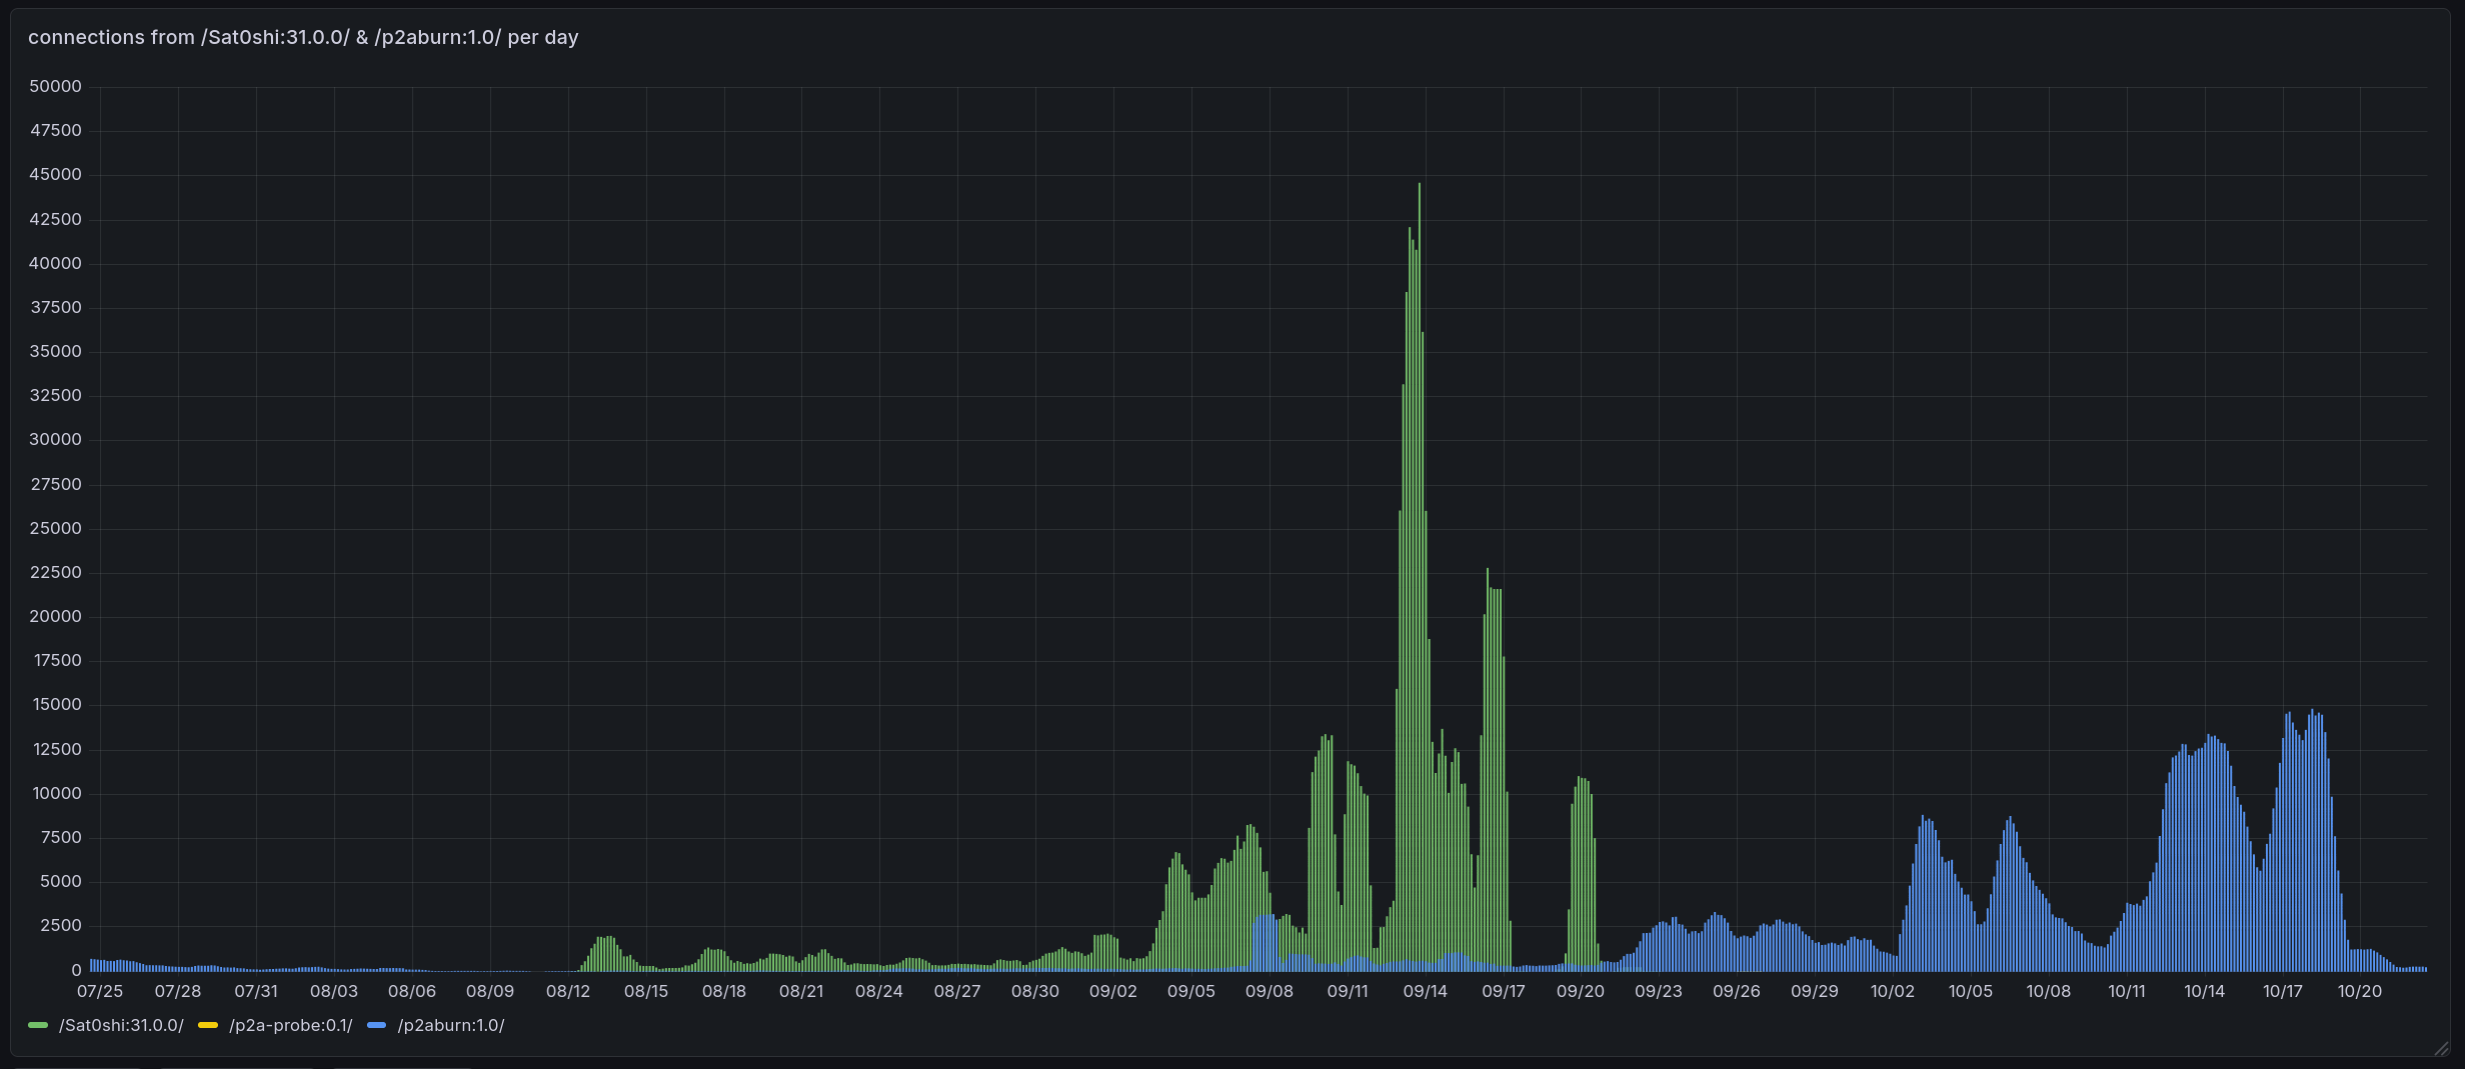
Since both seem to be re-connecting (probably because we kept evicting them), the number times we saw their version doesn’t indicate that they held X connections on that day.
---
### Author:  [@b10c](https://bnoc.xyz/u/b10c)
#### Post date: [October 22, 2026, 2:05pm UTC](https://bnoc.xyz/t/satoshi-31-0-0-peers-with-no-service-flags-and-protocol-70015-pushed-transactions-then-stopped-together-on-oct-18/193/8 "2026-10-22T14:05:38Z")
Found this:
>
Which doesn’t seem to be related at all. Sometimes searching for the user-agent on GitHub tells you more.
---
### Author:  [@stratospher](https://bnoc.xyz/u/stratospher)
#### Post date: [October 22, 2026, 8:12pm UTC](https://bnoc.xyz/t/satoshi-31-0-0-peers-with-no-service-flags-and-protocol-70015-pushed-transactions-then-stopped-together-on-oct-18/193/9 "2026-10-22T20:12:46Z")
thanks for bringing up `/p2aburn:1.0/` @benunskilled. didn’t know about it.
I do find the transactions which `/p2aburn:1.0/` sends us weird.
- the anchor burns are mostly rejected (though some make it into the mempool - 7k of them)
- `bad-txns-inputs-missingorspent` - anchor is already spent by the minter (28.4k)
- replacement with 0 additional fee (17.9k)
- replacement with less fee (1.7k)
- they also send us the minter’s transactions without the witness (12.4k rejects). maybe a software bug on their side?
---
### Author:  [@b10c](https://bnoc.xyz/u/b10c)
#### Post date: [October 22, 2026, 10:11pm UTC](https://bnoc.xyz/t/satoshi-31-0-0-peers-with-no-service-flags-and-protocol-70015-pushed-transactions-then-stopped-together-on-oct-18/193/10 "2026-10-22T22:11:23Z")
> [@stratospher](#):
>
> - `bad-txns-inputs-missingorspent` - anchor is already spent by the minter (28.4k)
> - replacement with 0 additional fee (17.9k)
> - replacement with less fee (1.7k)
- `bad-txns-inputs-missingorspent` could also mean that the inputs never existed.
- replacement with zero additional fees is likely and a slightly different version of that transaction. i.e. a double spend?
---
### Author:  [@m4ycon](https://bnoc.xyz/u/m4ycon)
#### Post date: [October 22, 2026, 11:07pm UTC](https://bnoc.xyz/t/satoshi-31-0-0-peers-with-no-service-flags-and-protocol-70015-pushed-transactions-then-stopped-together-on-oct-18/193/11 "2026-10-22T23:07:43Z")
As it also touches this post, I have found `/txbroadcast:0.1/` that seems to act similarly as `/Sat0shi:31.0.0/` and `/Satoshi:31.0.0/ + 70015`, it appeared a bit before `Sat0shi`. More details on [#198](https://bnoc.xyz/t/compact-block-reconstruction-degradation/198).